⚡ Performance and Efficiency Benchmarks
This section reports the performance on NPU with FastFlowLM (FLM).
Note:
- Results are based on FastFlowLM v1.0.4.
- Under FLM’s default NPU power mode (Performance)
- Newer versions may deliver improved performance.
- Fine-tuned models show performance comparable to their base models.
Test System 1:
AMD Ryzen™ AI 7 350 (Kraken Point) with 32 GB DRAM; performance is comparable to other Kraken Point systems.
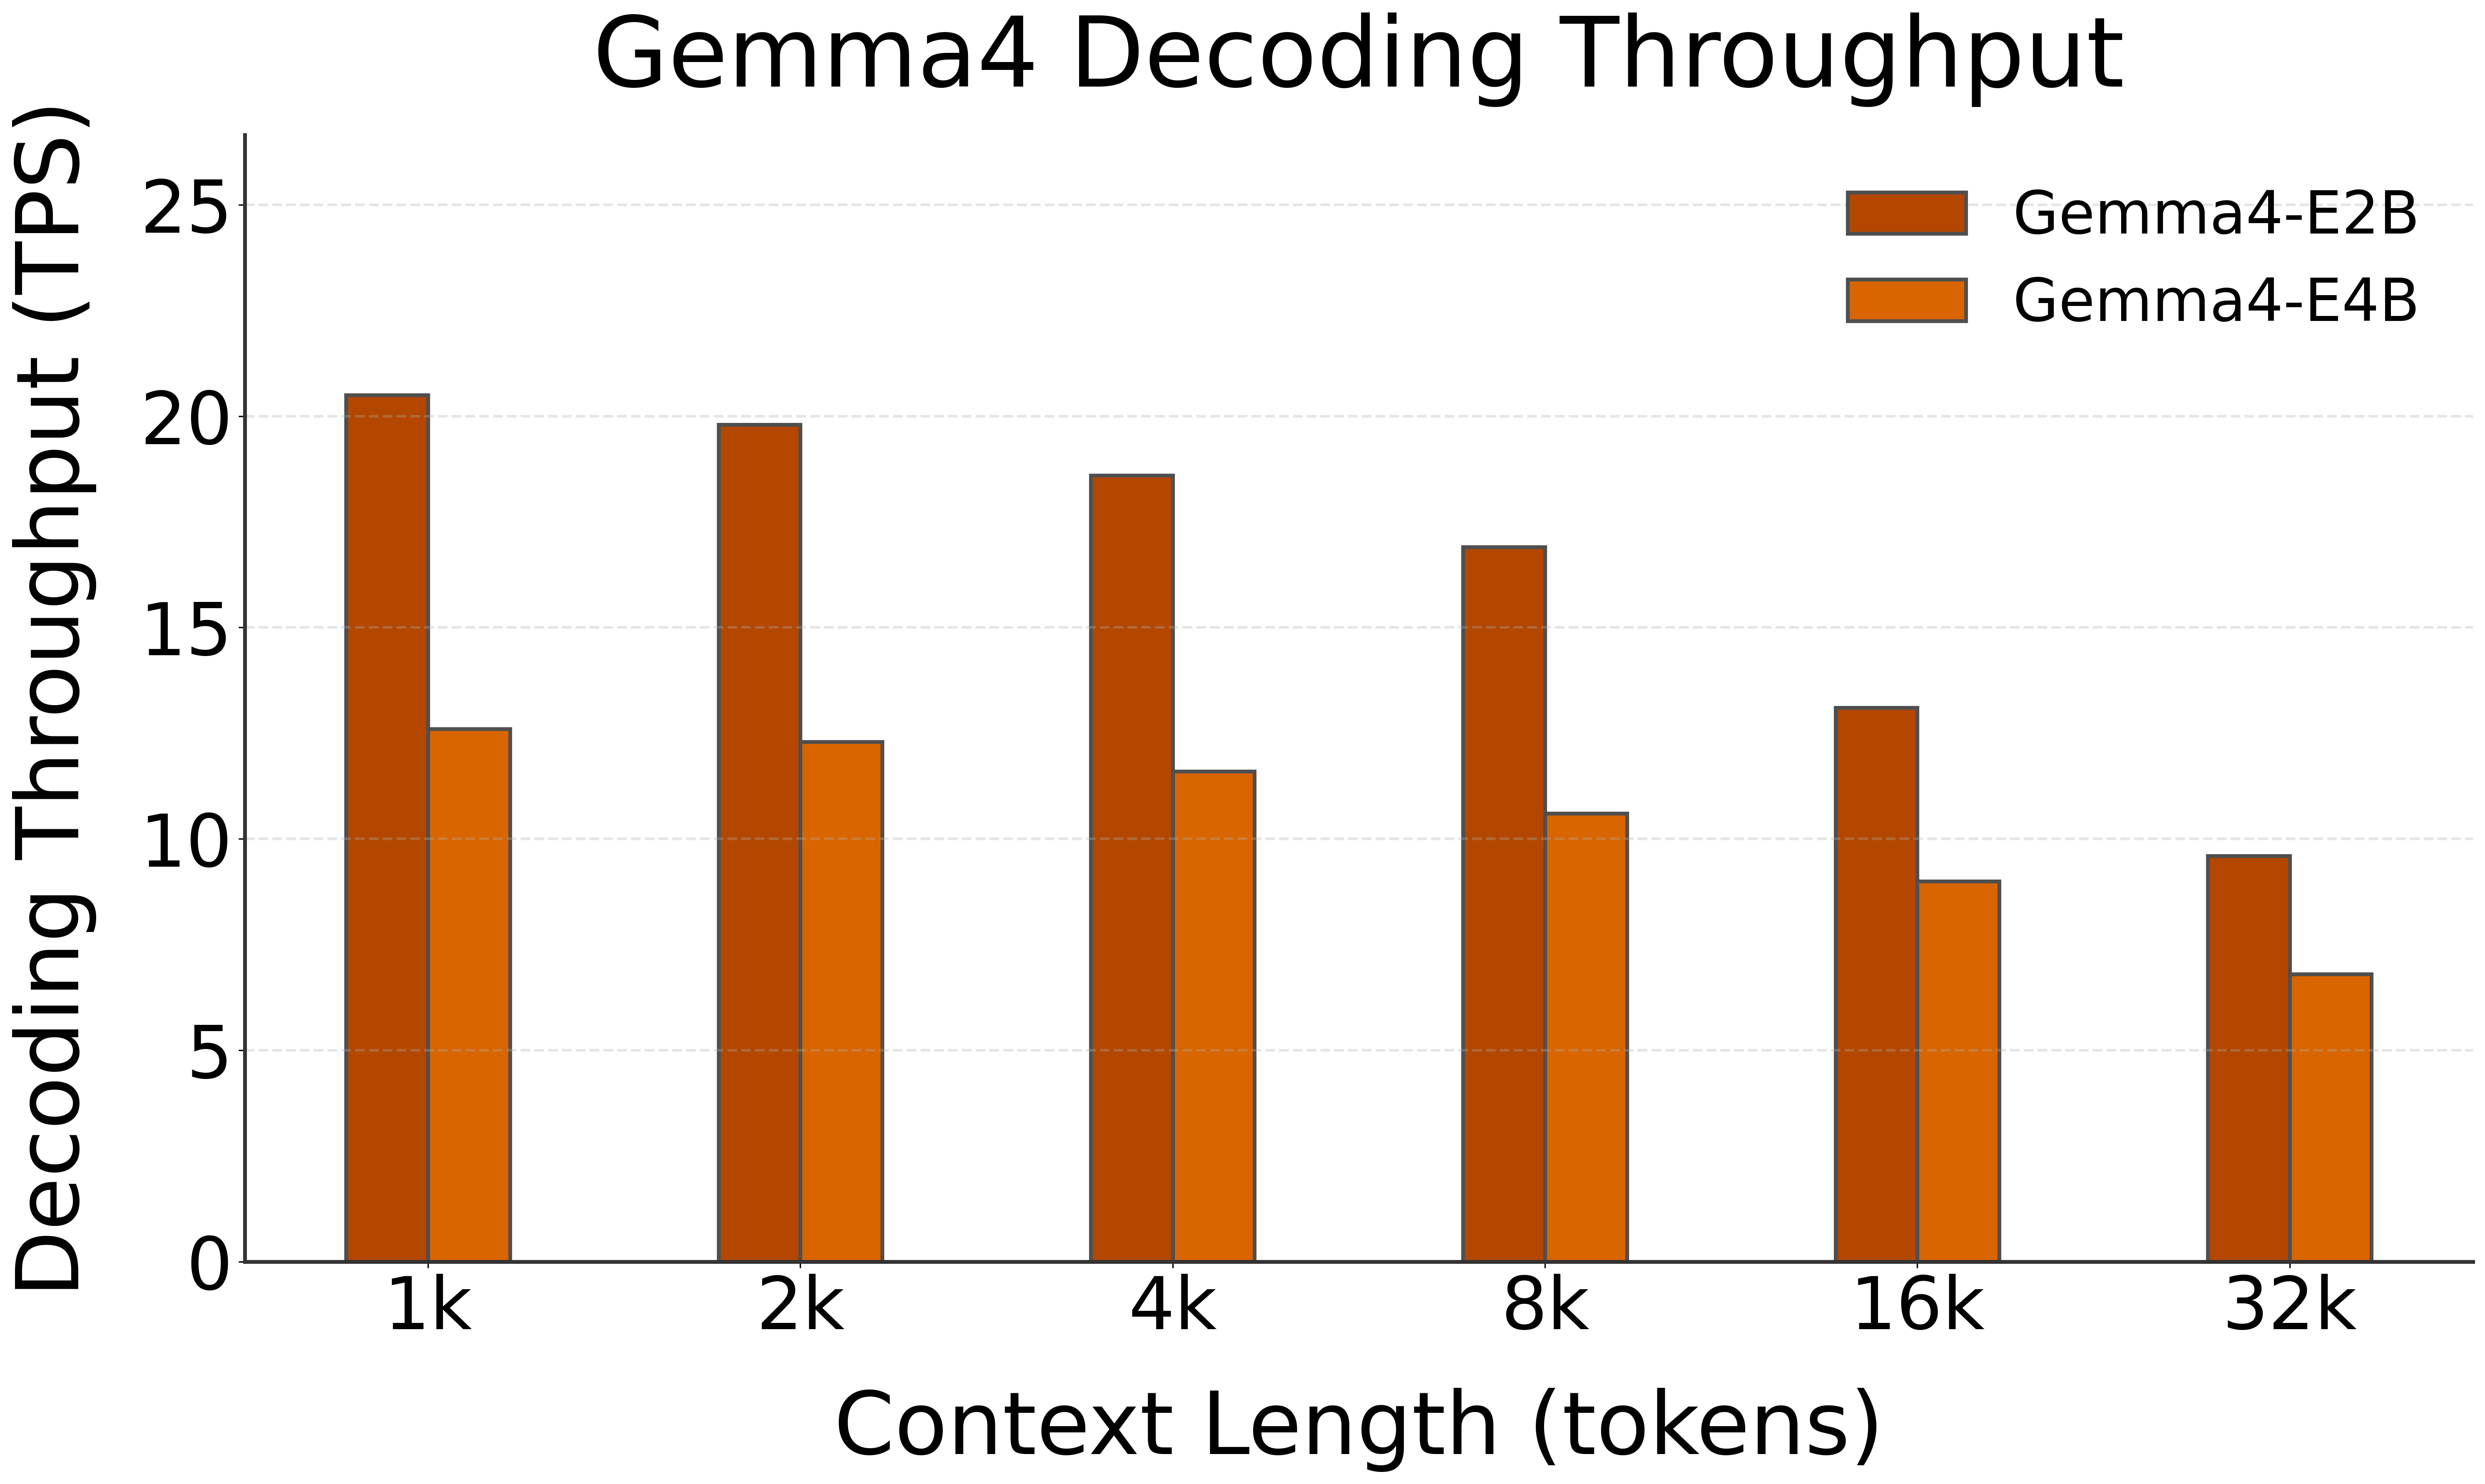
🚀 Decoding Speed (TPS, or Tokens per Second, starting @ different context lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|---|
| Gemma 4 E2B | NPU (FLM) | 22.6 | 21.7 | 20.0 | 17.5 | 14.1 | 10.1 |
| Gemma 4 E4B | NPU (FLM) | 12.6 | 12.3 | 11.6 | 10.6 | 9.0 | 6.8 |
| Gemma 4 12B | NPU (FLM) | 6.3 | 6.3 | 6.2 | 6.1 | 5.9 | 5.6 |
Each LLM has a maximum supported context window. For example, the gemma4-it:e2b model supports up to 128k tokens.
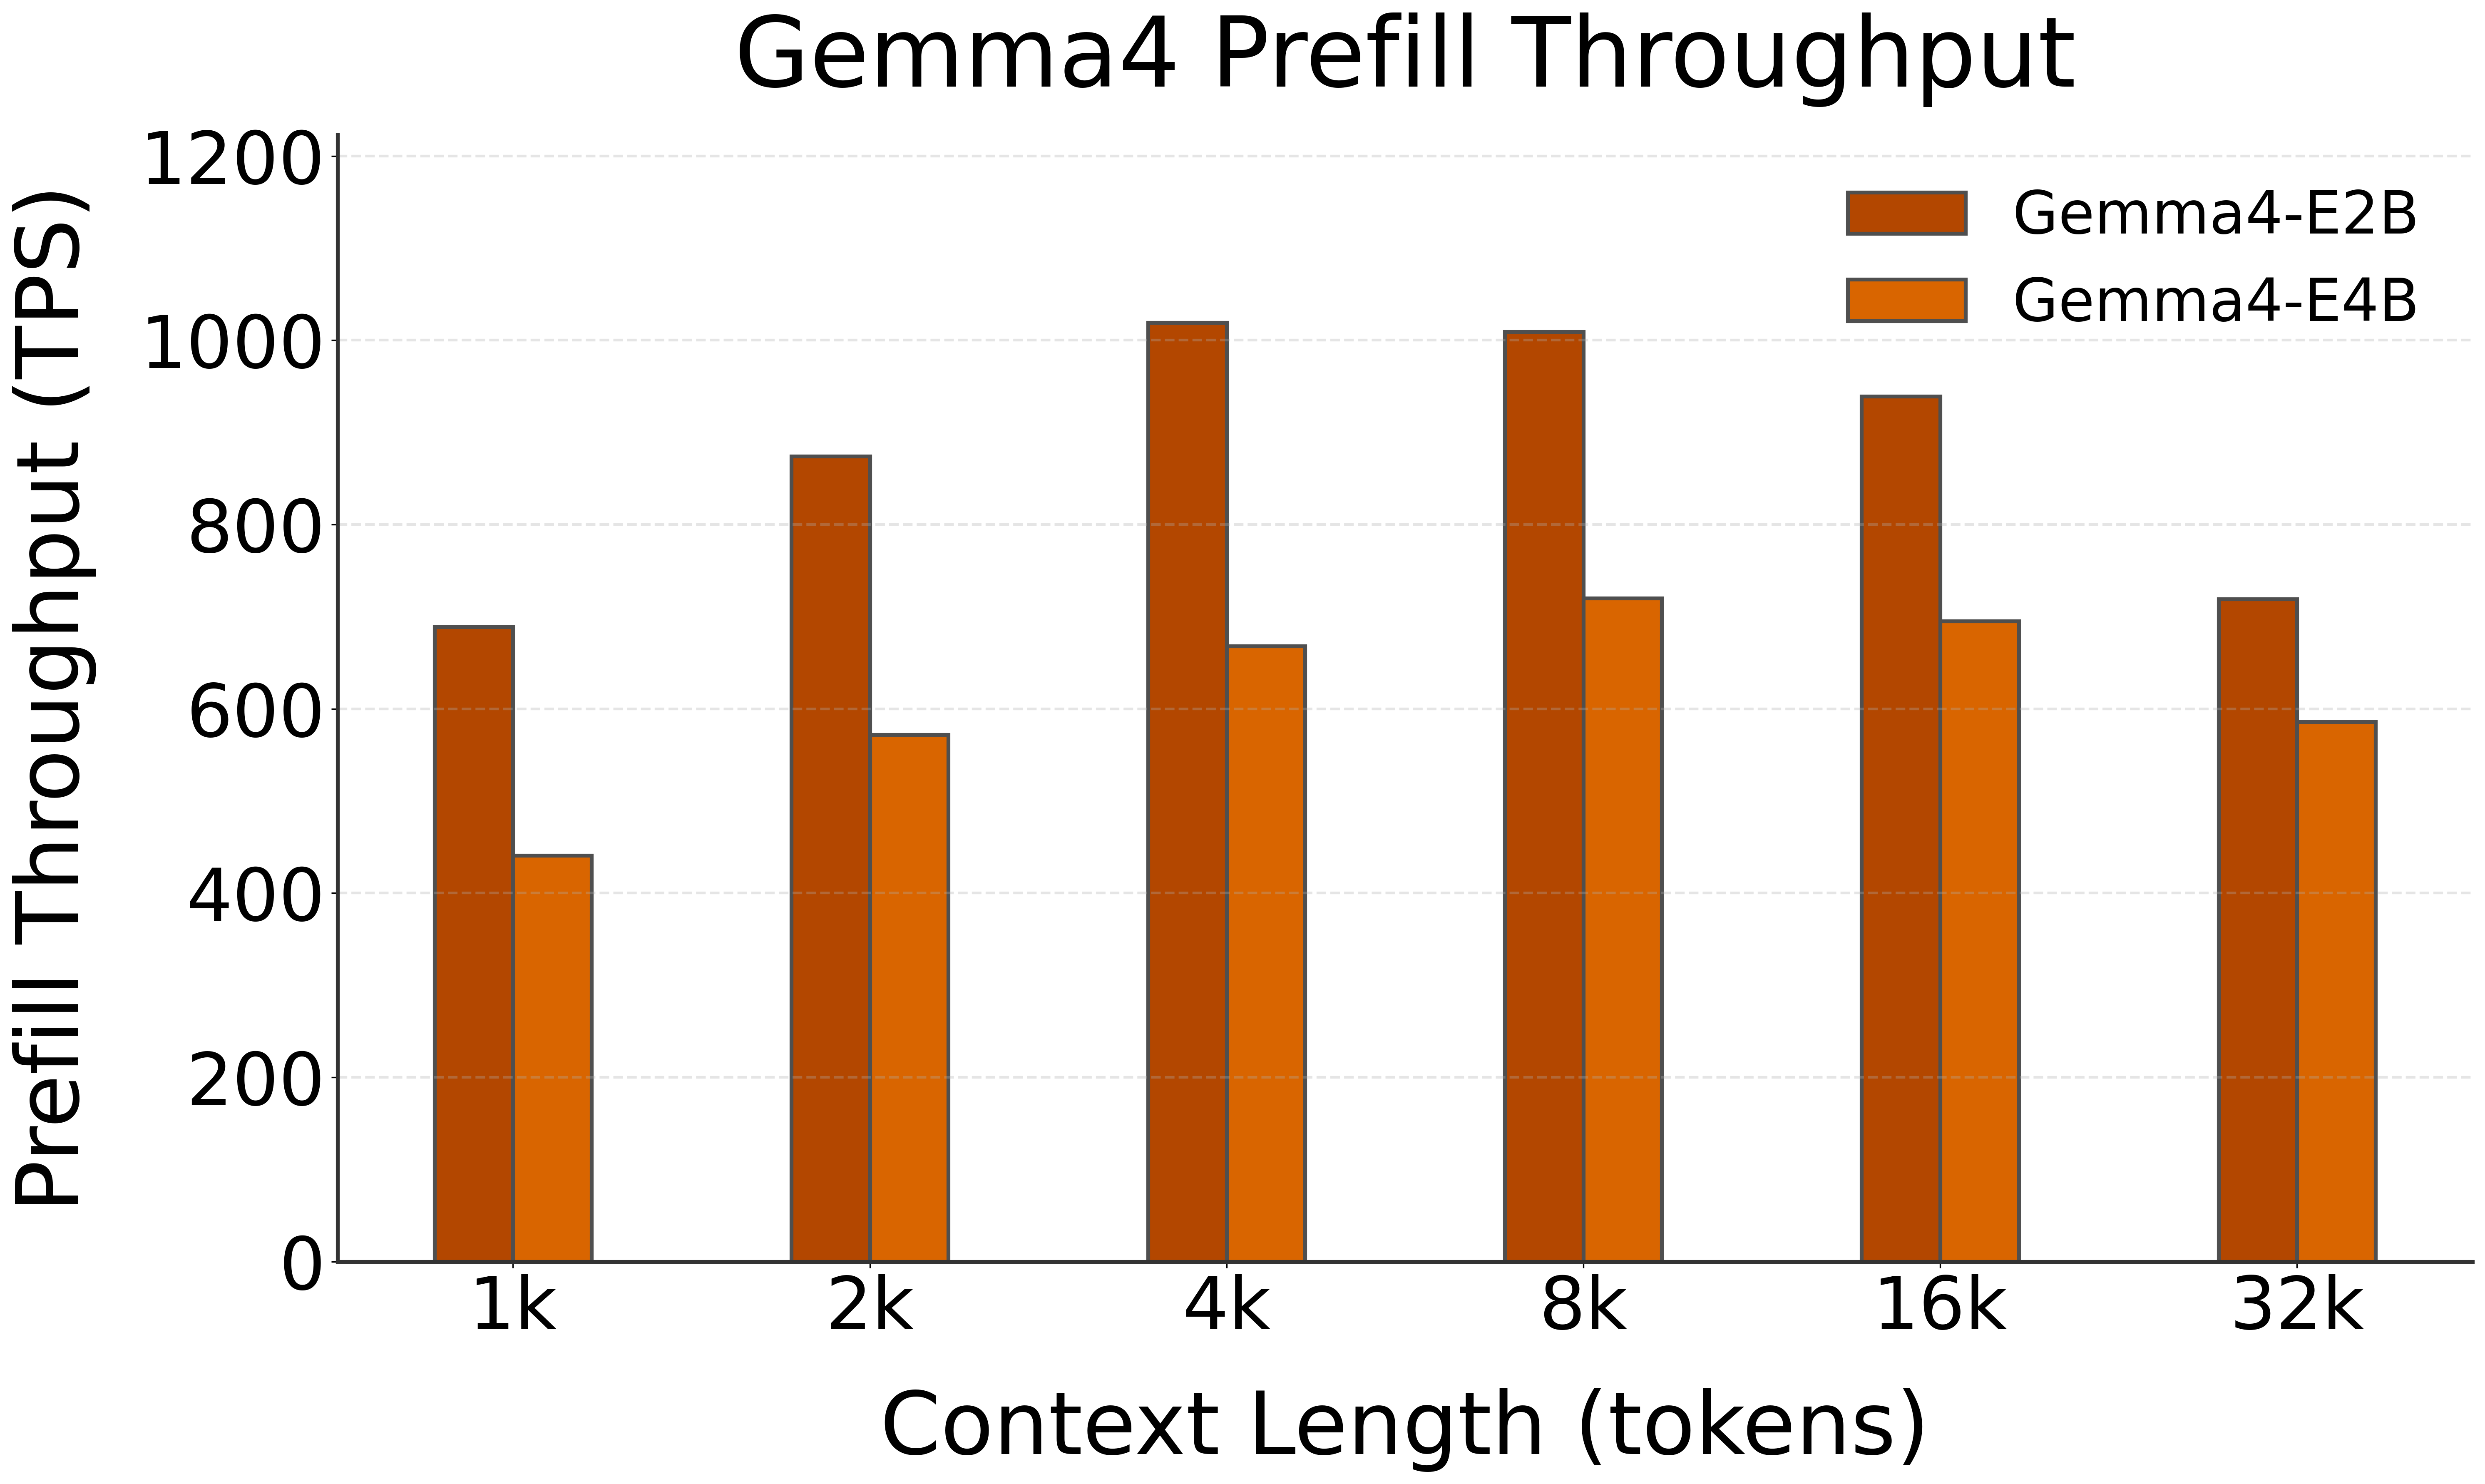
🚀 Prefill Speed (TPS, or Tokens per Second, with different prompt lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|---|
| Gemma 4 E2B | NPU (FLM) | 721 | 945 | 1086 | 1124 | 1028 | 783 |
| Gemma 4 E4B | NPU (FLM) | 441 | 572 | 668 | 720 | 695 | 586 |
| Gemma 4 12B | NPU (FLM) | 155 | 217 | 272 | 298 | 297 | 261 |
🚀 Prefill TTFT with Image (Seconds)
| Model | HW | Image |
|---|---|---|
| Gemma 4 E2B | NPU (FLM) | 1.7 |
| Gemma 4 E4B | NPU (FLM) | 1.75 |
| Gemma 4 12B | NPU (FLM) | 3.4 |
This test uses a short prompt: “Describe this image.”