⚡ Performance and Efficiency Benchmarks
This section reports the performance on NPU with FastFlowLM (FLM).
Note:
- Results are based on FastFlowLM v0.9.30.
- Under FLM’s default NPU power mode (Performance)
- Newer versions may deliver improved performance.
- Fine-tuned models show performance comparable to their base models.
Test System 1:
AMD Ryzen™ AI 7 350 (Kraken Point) with 32 GB DRAM; performance is comparable to other Kraken Point systems.
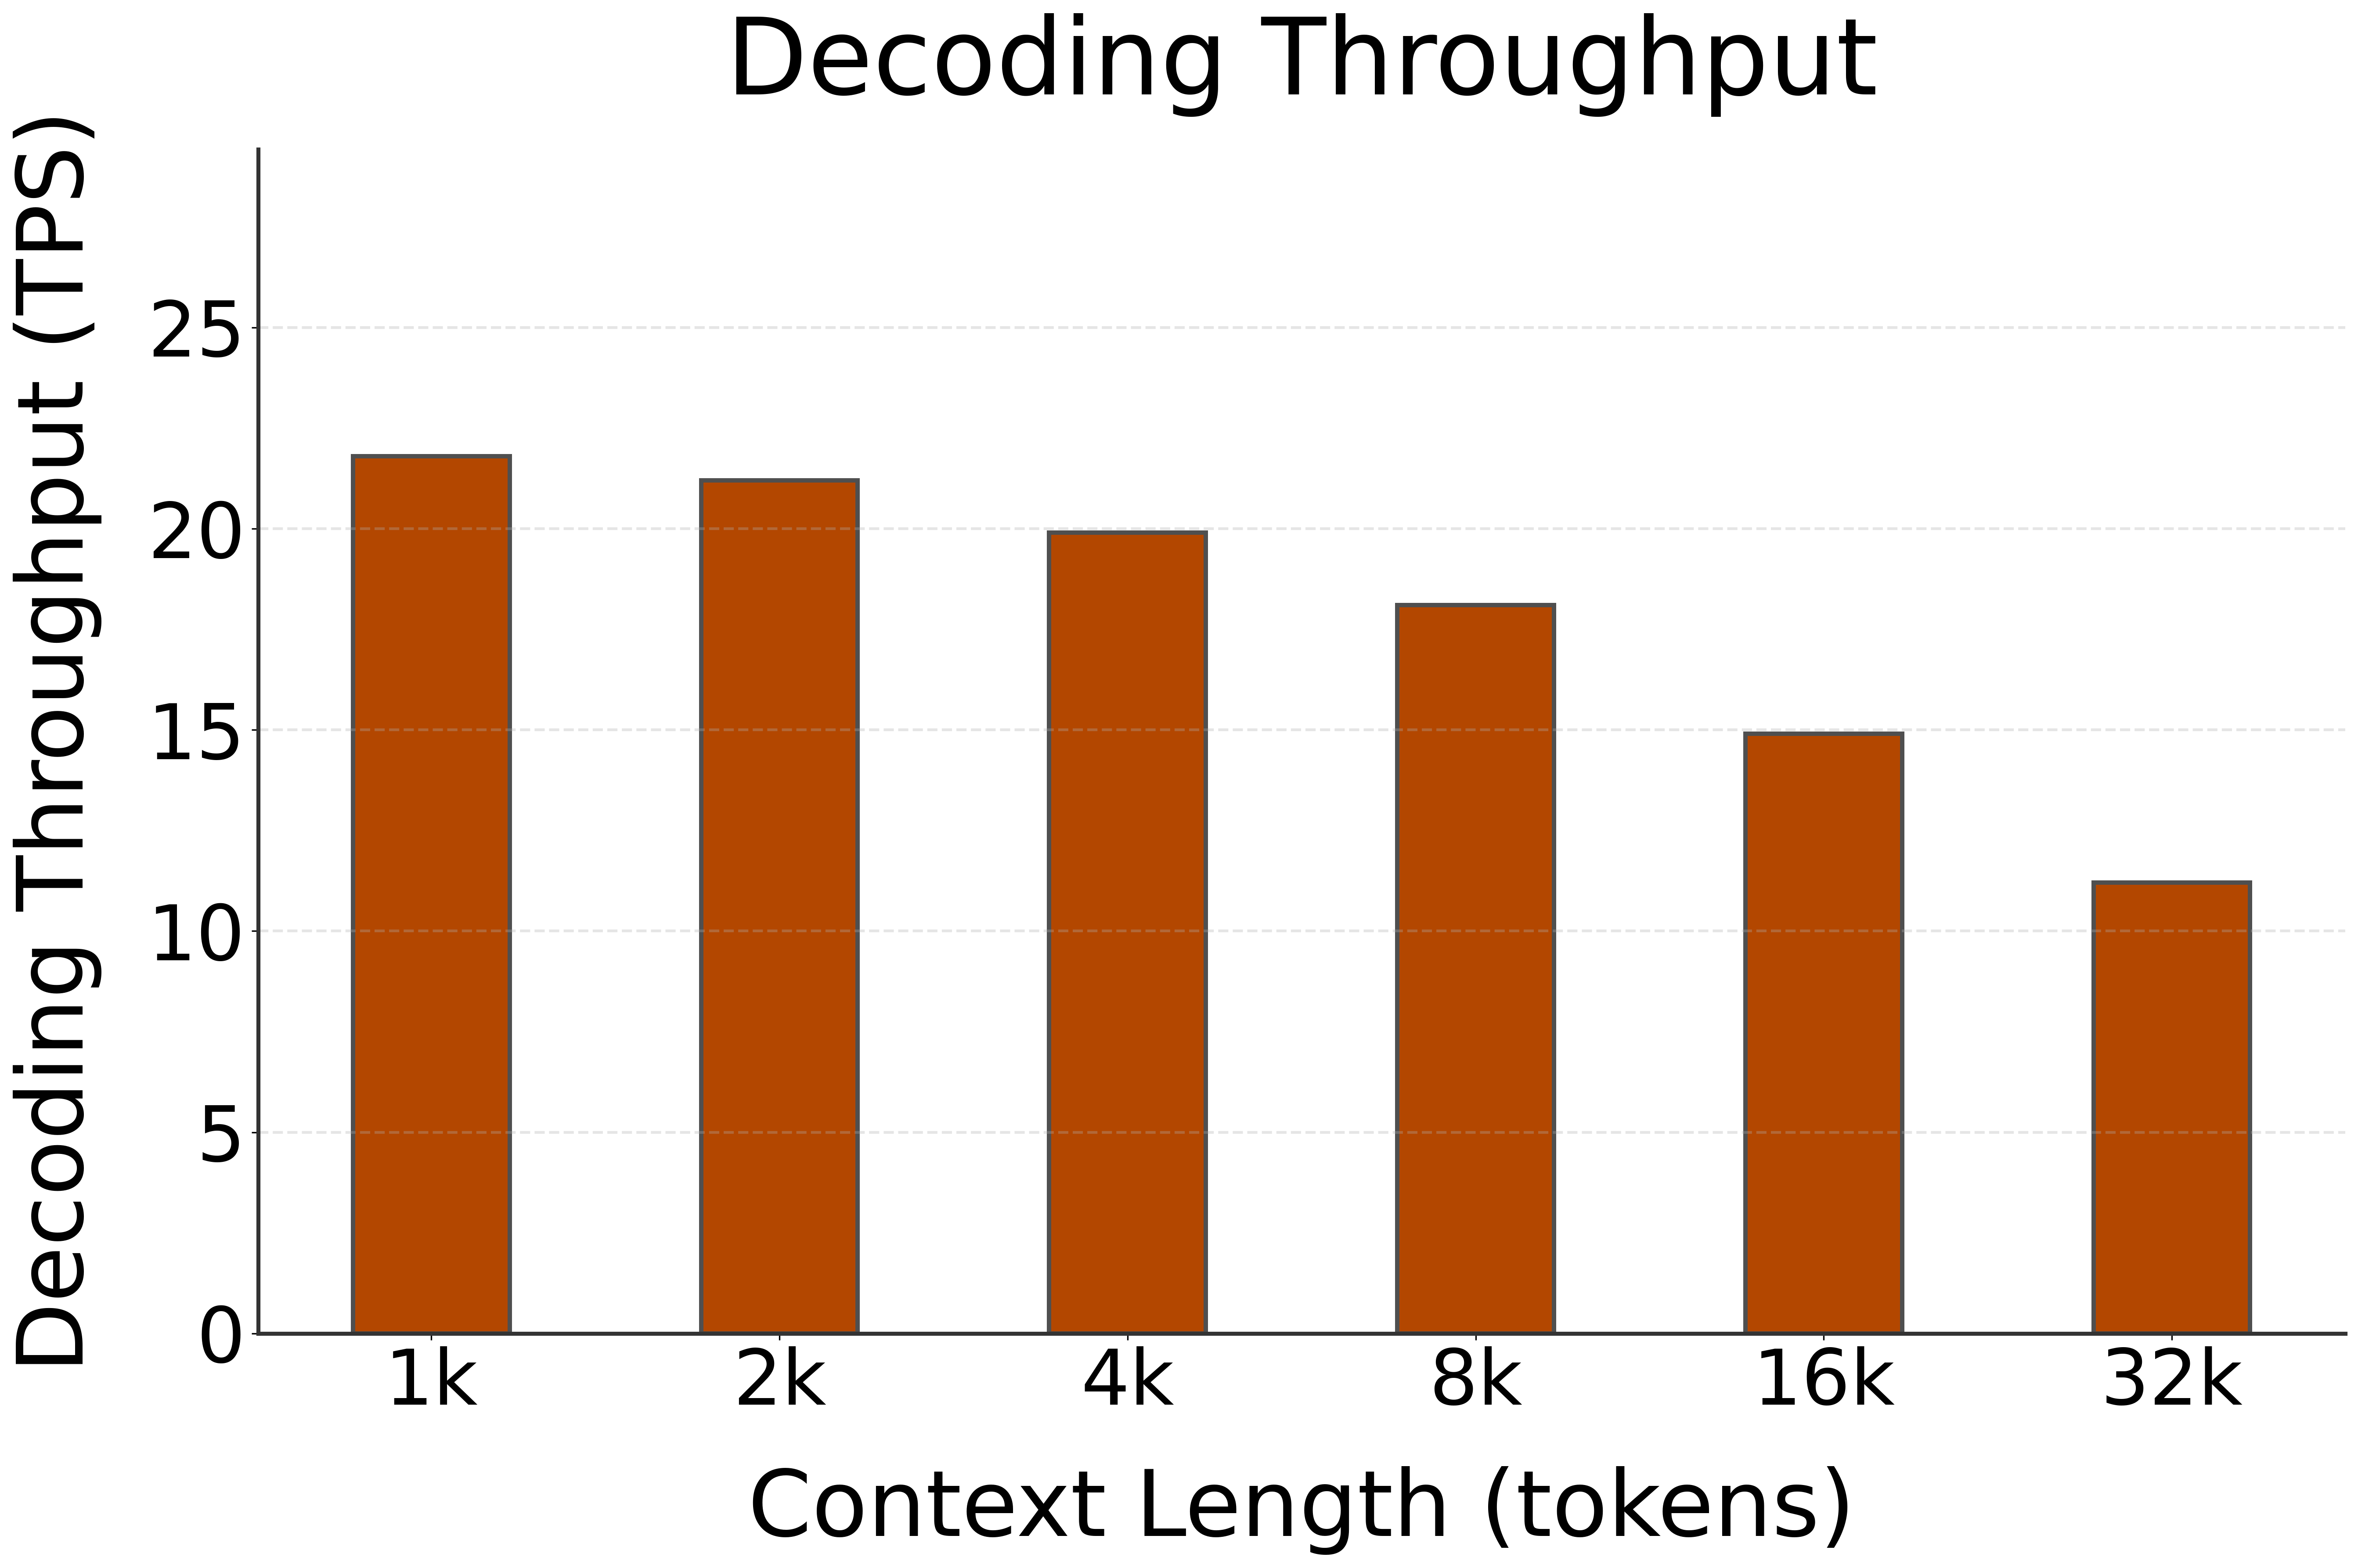
🚀 Decoding Speed (TPS, or Tokens per Second, starting @ different context lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|---|
| Phi-4-mini-instruct | XDNA2 | 21.8 | 21.2 | 19.9 | 18.1 | 14.9 | 11.2 |
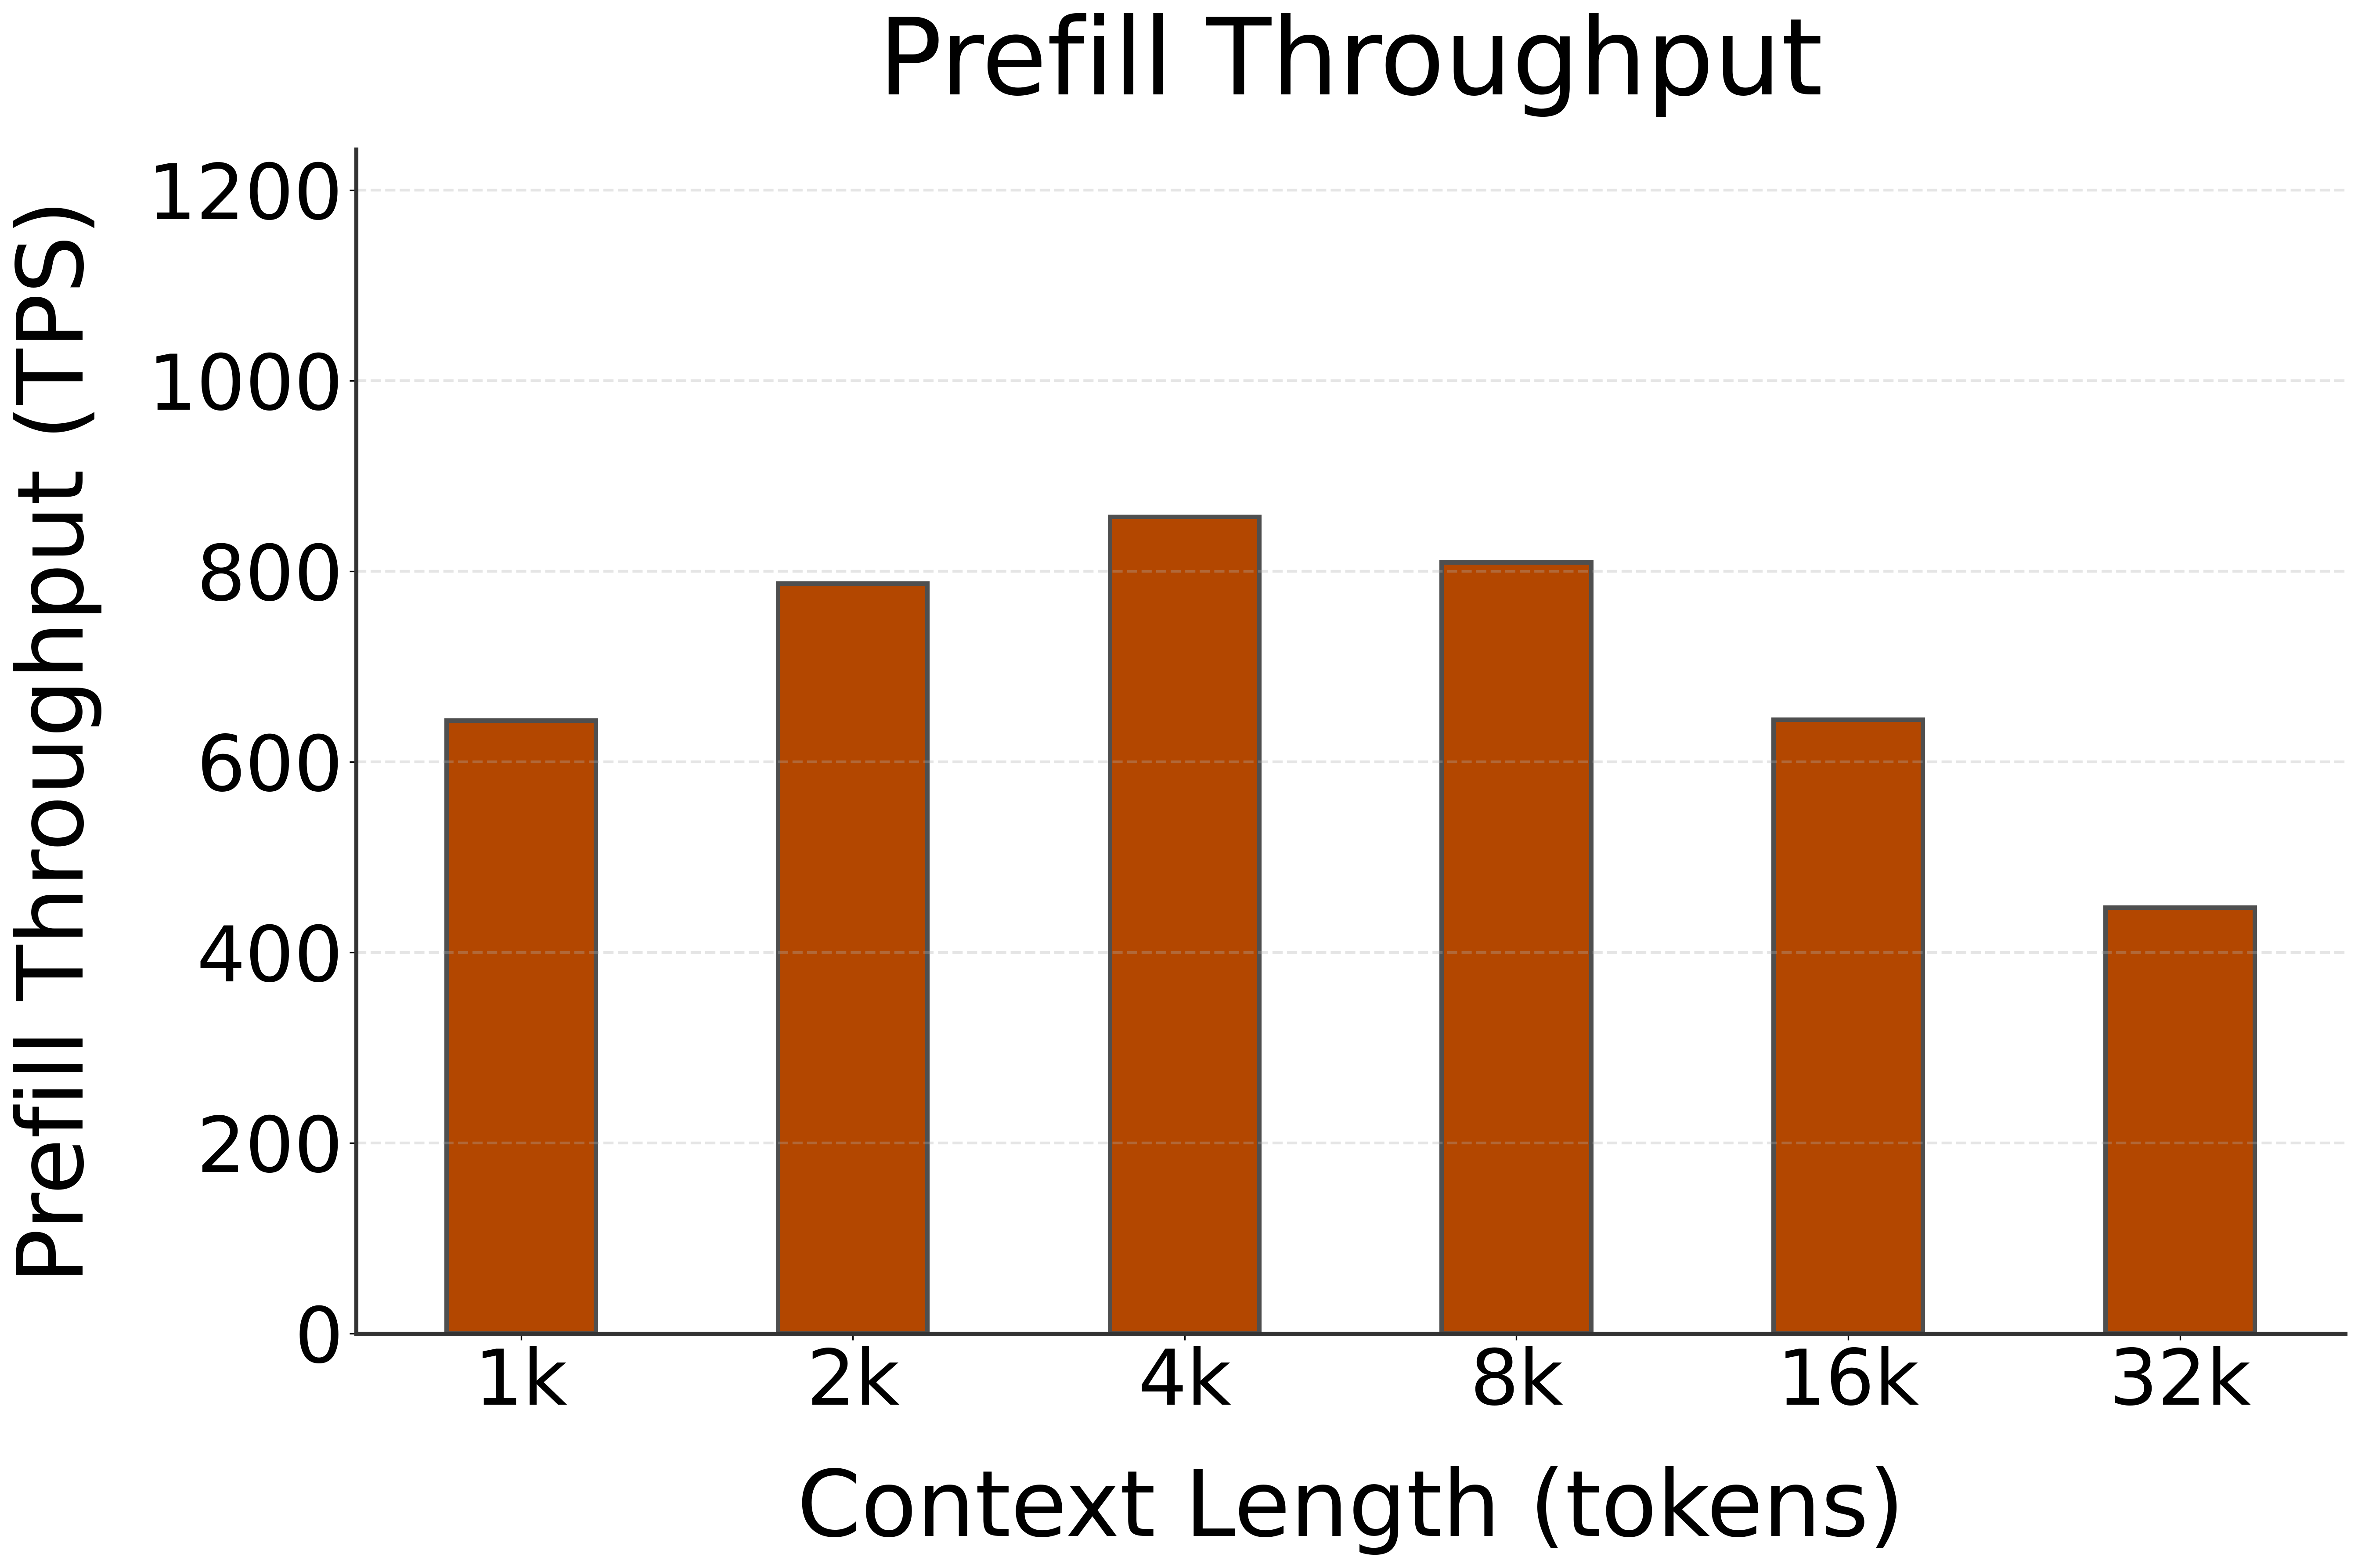
🚀 Prefill Speed (TPS, or Tokens per Second, with different prompt lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k | 32k |
|---|---|---|---|---|---|---|---|
| Phi-4-mini-instruct | XDNA2 | 643 | 787 | 857 | 809 | 644 | 447 |
🧪 Phi-4-mini-instruct Q8_0 GGUF on the core backend (phi4-mini-it-core:4b, dev04)
These are descriptive measurements from individual runs, not a benchmark sweep and not a pass threshold. Each figure below comes from one run, not from an average over many. They are not comparable to the tables above, which sweep 1k–32k on NPU2.
Provenance
| Machine | dev04 development machine |
| OS | Microsoft Windows 11 Enterprise 10.0.26100 |
| FastFlowLM commit | 16943bc4 |
| corelib commit / version | a8c6e8d / 0.11.0, built from source, loaded from beside flm.exe |
| Run | 2026-10-01, flm serve phi4-mini-it-core:4b --ctx-len 4096, /api/generate with max_tokens: 8 |
Measurements
One server, four prompts in increasing length, each a fresh conversation. The 64-token row is the server’s first request and carries one-time setup.
| Prompt tokens | Prefill | Prefill rate | Decode (8 tokens) |
|---|---|---|---|
| 67 | 0.16 s | ~410 tok/s | 42.7 tok/s |
| 259 | 0.12 s | ~2,100 tok/s | 47.3 tok/s |
| 1,027 | 0.62 s | ~1,660 tok/s | 42.1 tok/s |
| 2,051 | 1.59 s | ~1,290 tok/s | 40.7 tok/s |
Model load was 1.0–1.2 s (Model loaded in, as reported by FLM). Every reply
was a coherent continuation of the prompt, and the server log reports
Backend: core (from model catalog).
Not measured at this version: cold and warm TTFT in isolation, and the cancellation and capacity-boundary checks.