⚡ Performance and Efficiency Benchmarks
This section reports the performance on NPU with FastFlowLM (FLM).
Note:
- The 1k, 2k and 4k columns are based on FastFlowLM v1.0.13 (Q4_K weights); the 8k and 16k columns are still from v1.0.5 (Q4_0 weights) and are not directly comparable.
- Under FLM’s default NPU power mode (Performance)
- Newer versions may deliver improved performance.
- Hy-MT2 is a dedicated translation model tuned for short, single-turn requests, so it is benchmarked up to 16k max context length rather than the longer sweeps used for general chat models.
Test System:
AMD Ryzen™ AI 9 370 (Strix Point) with 32 GB DRAM; performance is comparable to other Strix Point and Strix Halo systems.
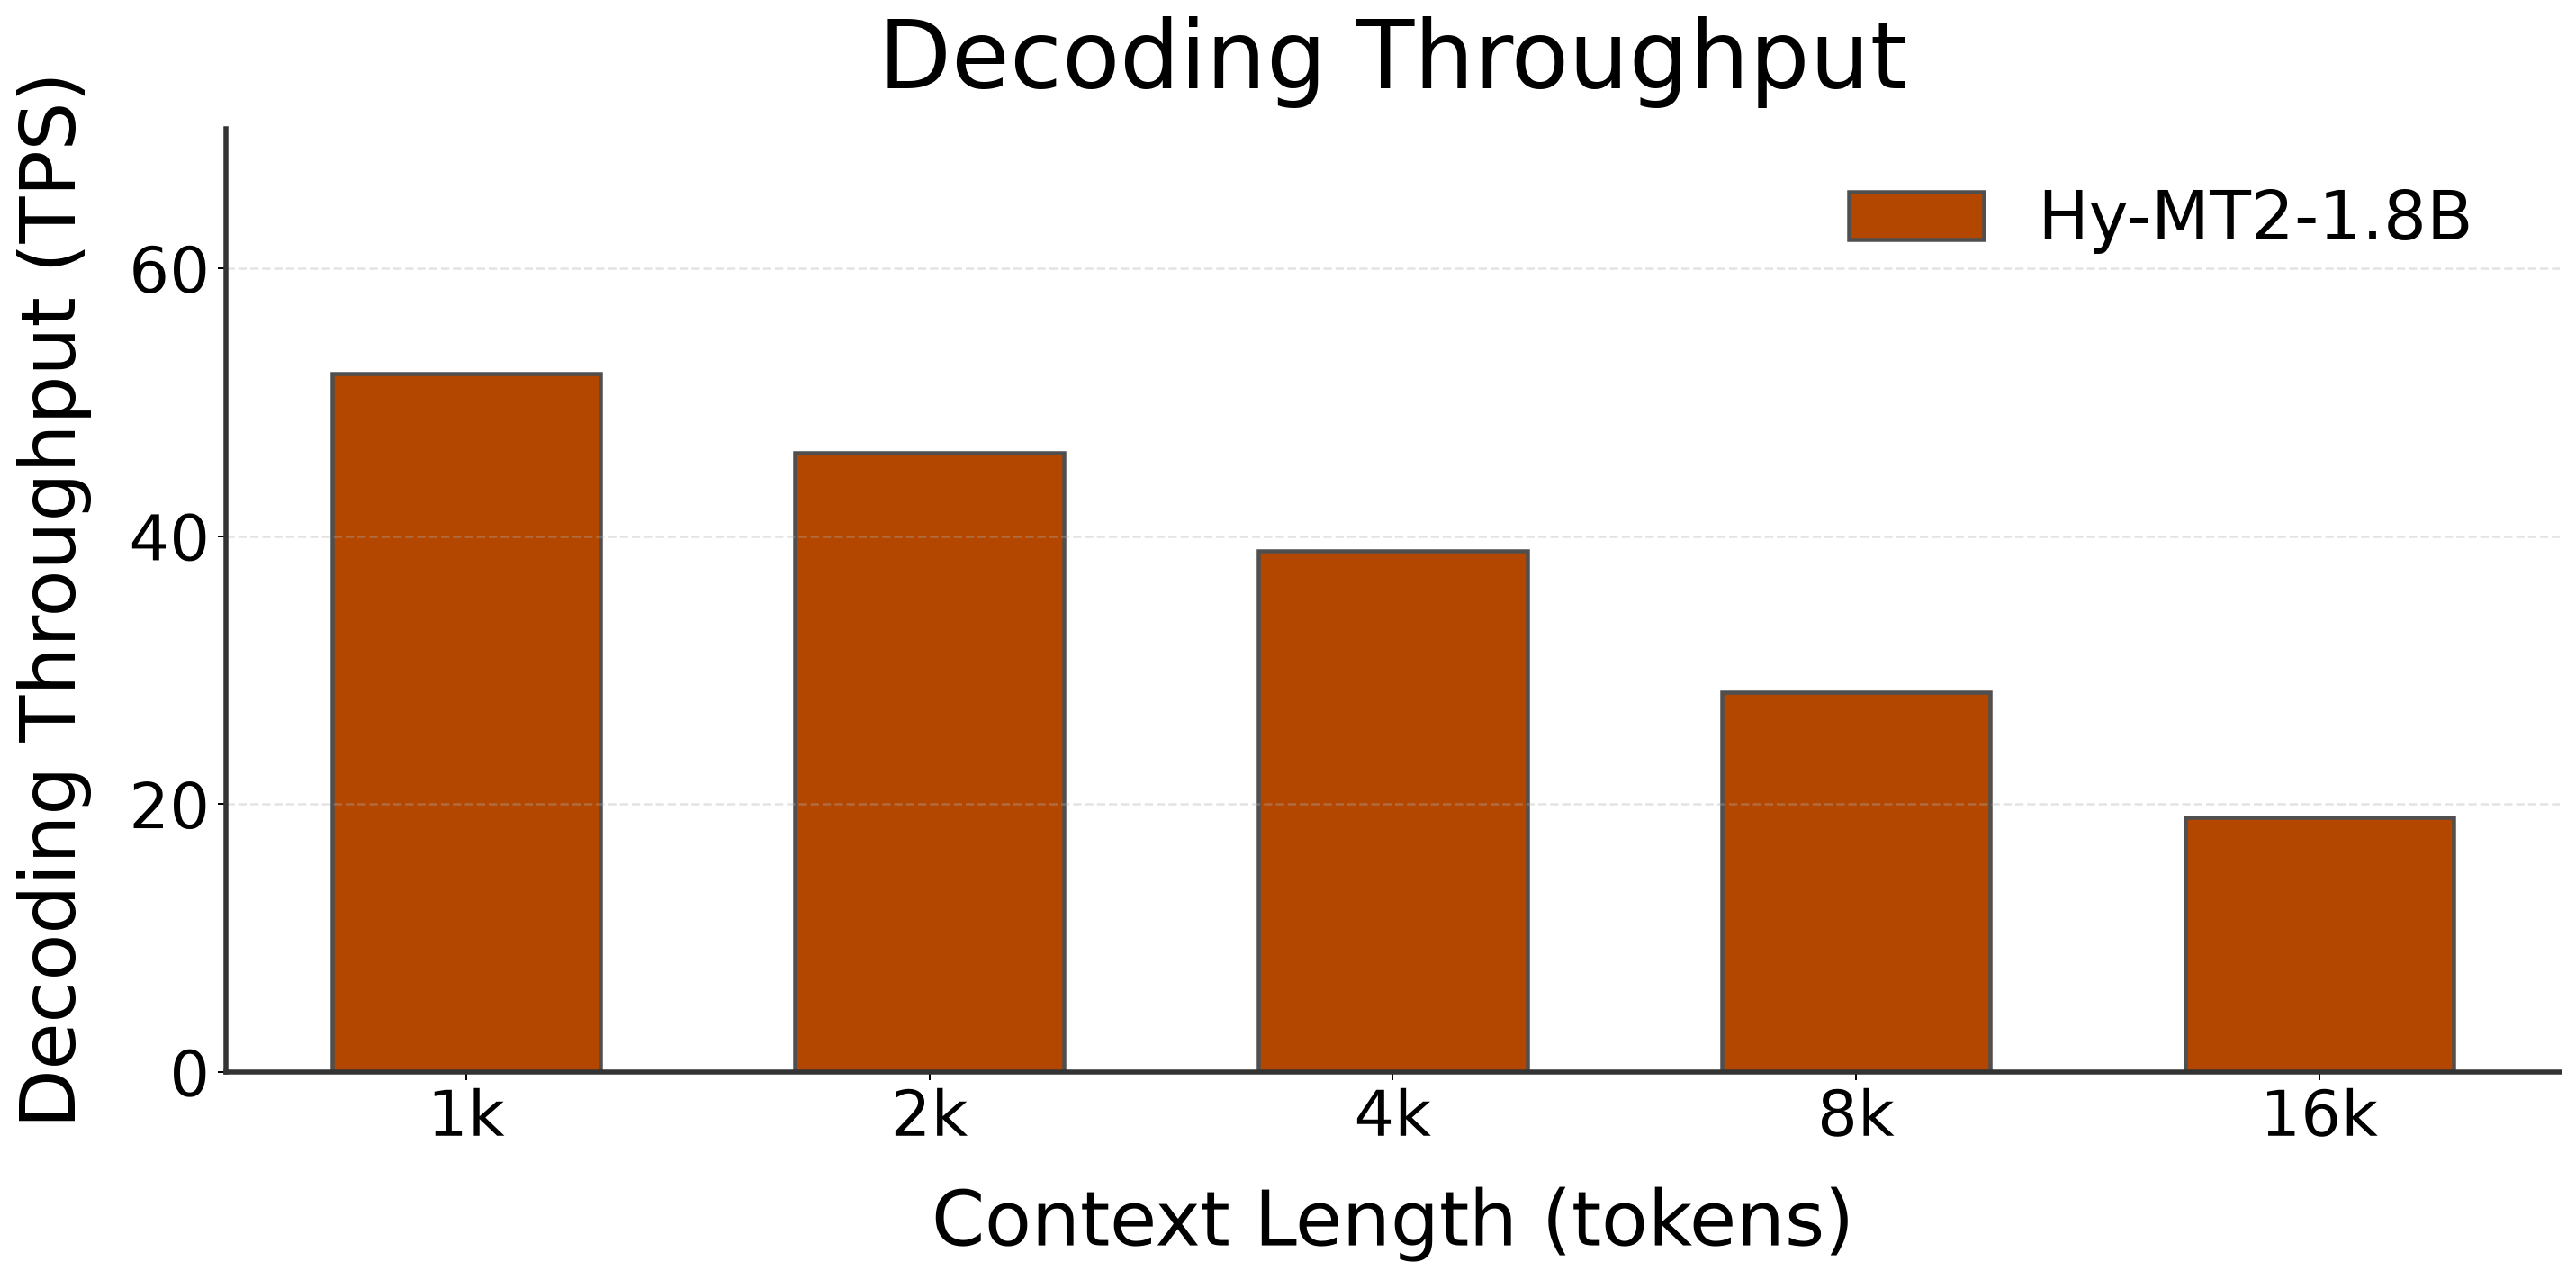
🚀 Decoding Speed (TPS, or Tokens per Second, starting @ different context lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k |
|---|---|---|---|---|---|---|
| Hy-MT2-1.8B | XDNA2 | 43.2 | 41.5 | 38.9 | 28.4 | 19 |
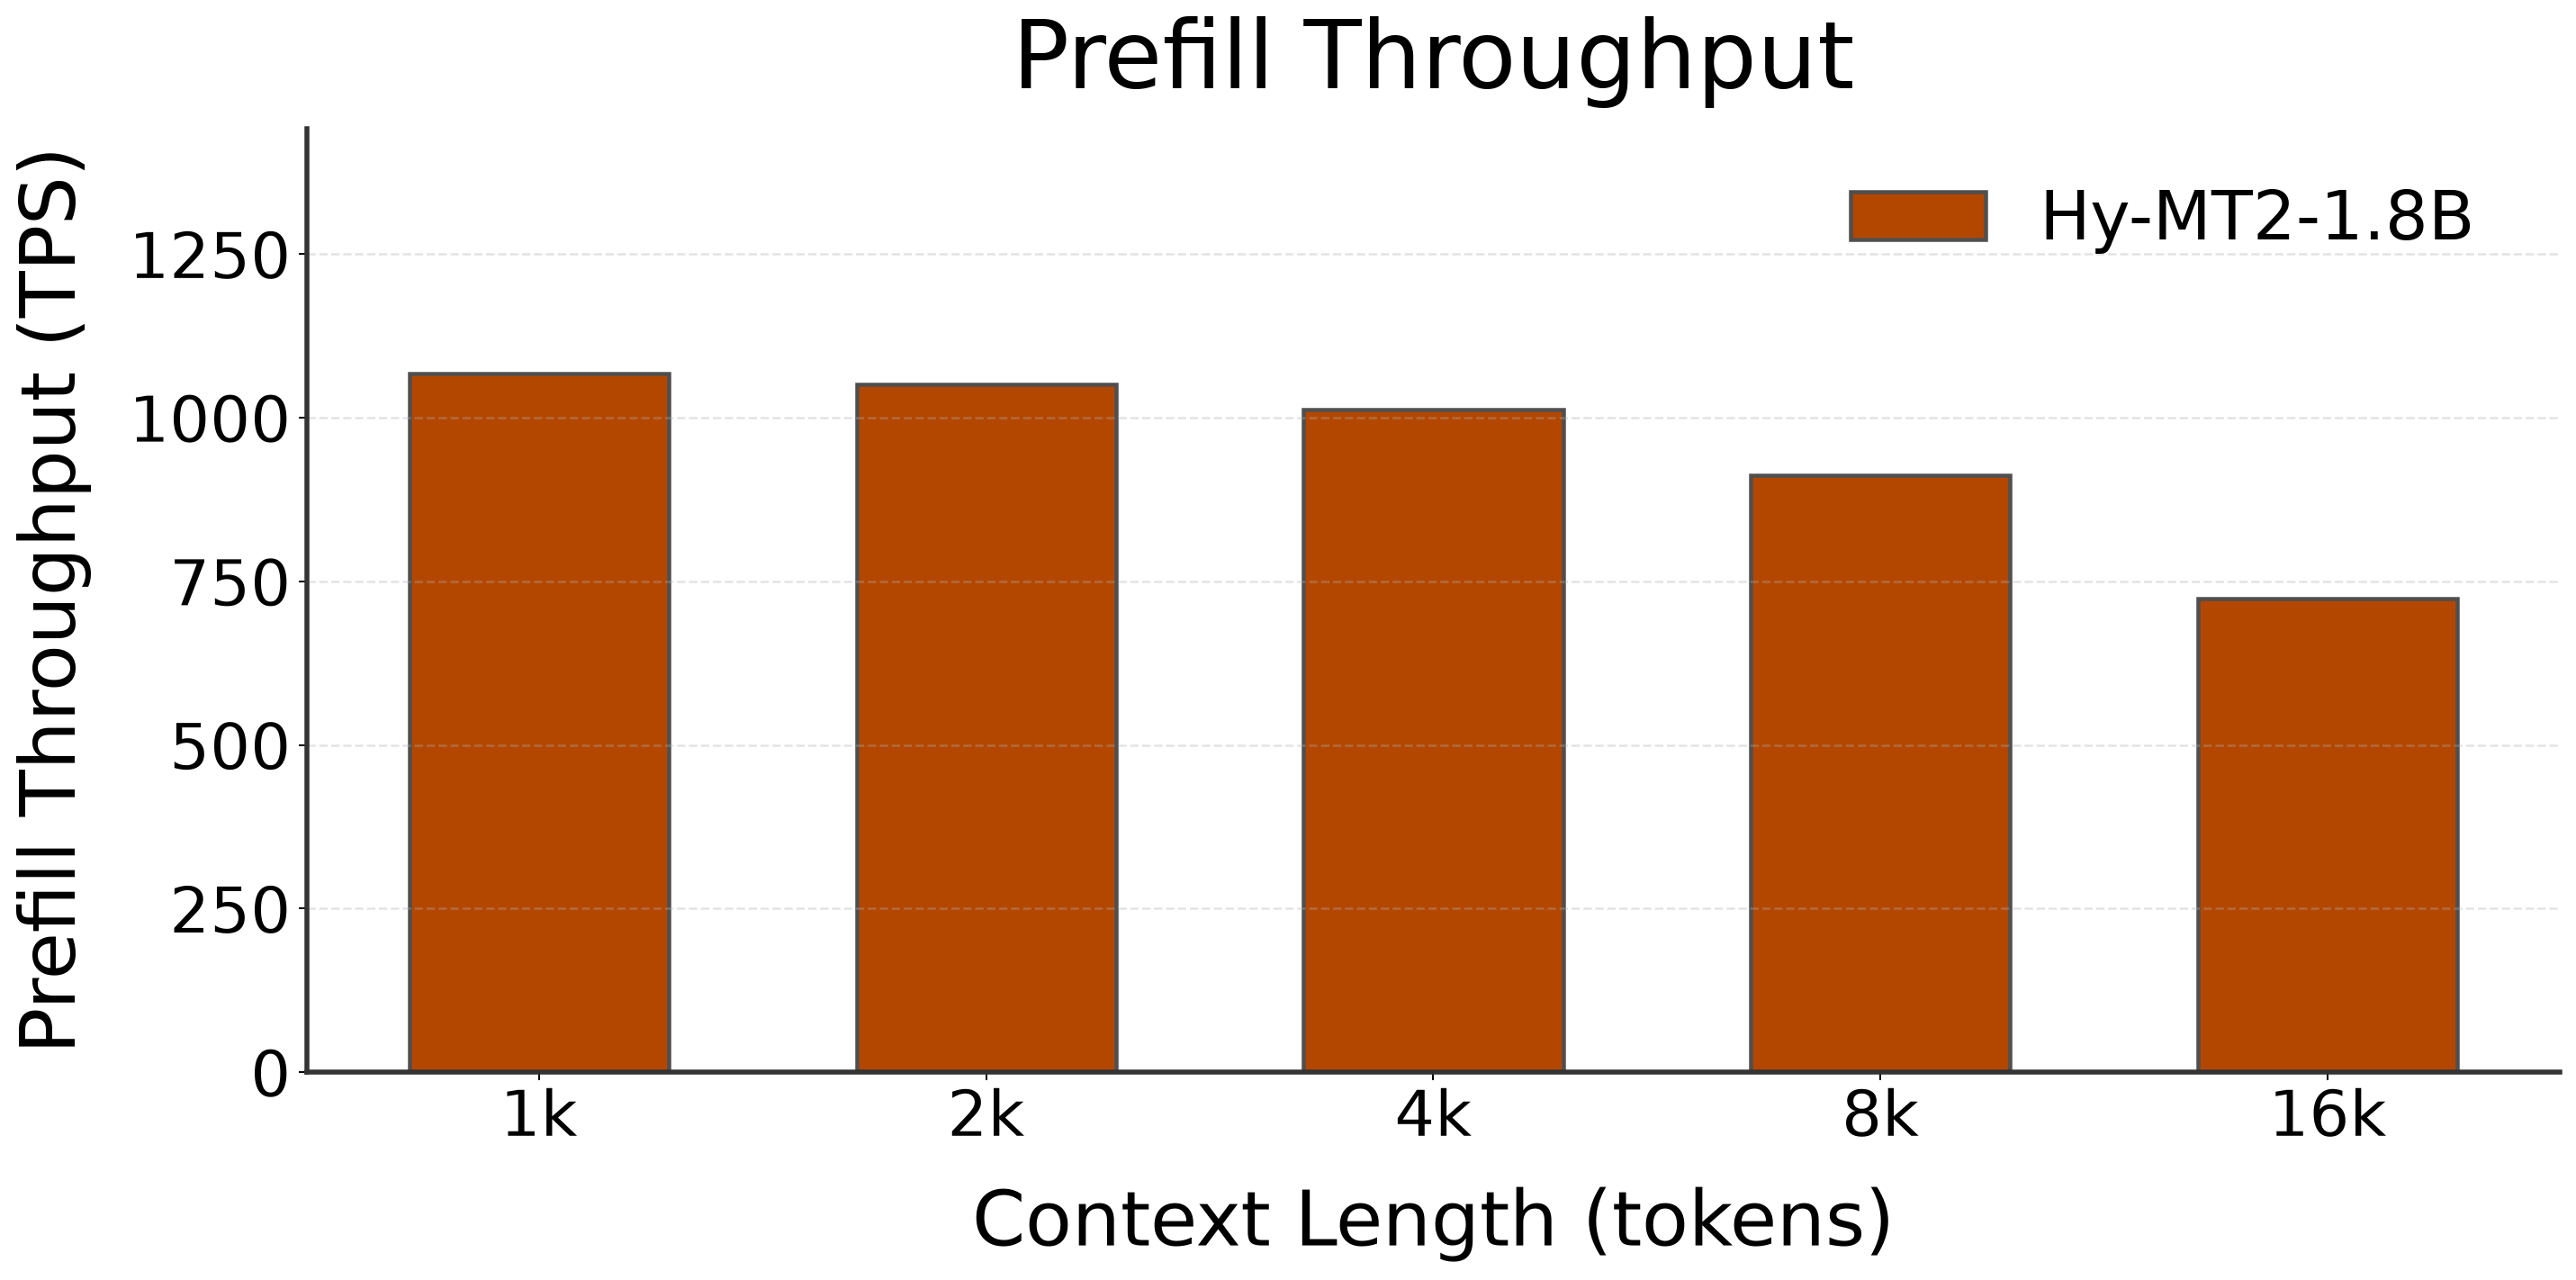
🚀 Prefill Speed (TPS, or Tokens per Second, with different prompt lengths)
| Model | HW | 1k | 2k | 4k | 8k | 16k |
|---|---|---|---|---|---|---|
| Hy-MT2-1.8B | XDNA2 | 1,701 | 1,574 | 1,388 | 912 | 723 |